**번역본뉴스입니다. 오역이 있을수 있습니다.
Gemini 4 Carbon은 이번 주 일부 사이버 보안 방어자를 대상으로 순차 배포를 시작하며, 안전장치 검증을 거친 후 일반 접근 권한을 점진적으로 확대할 계획입니다.
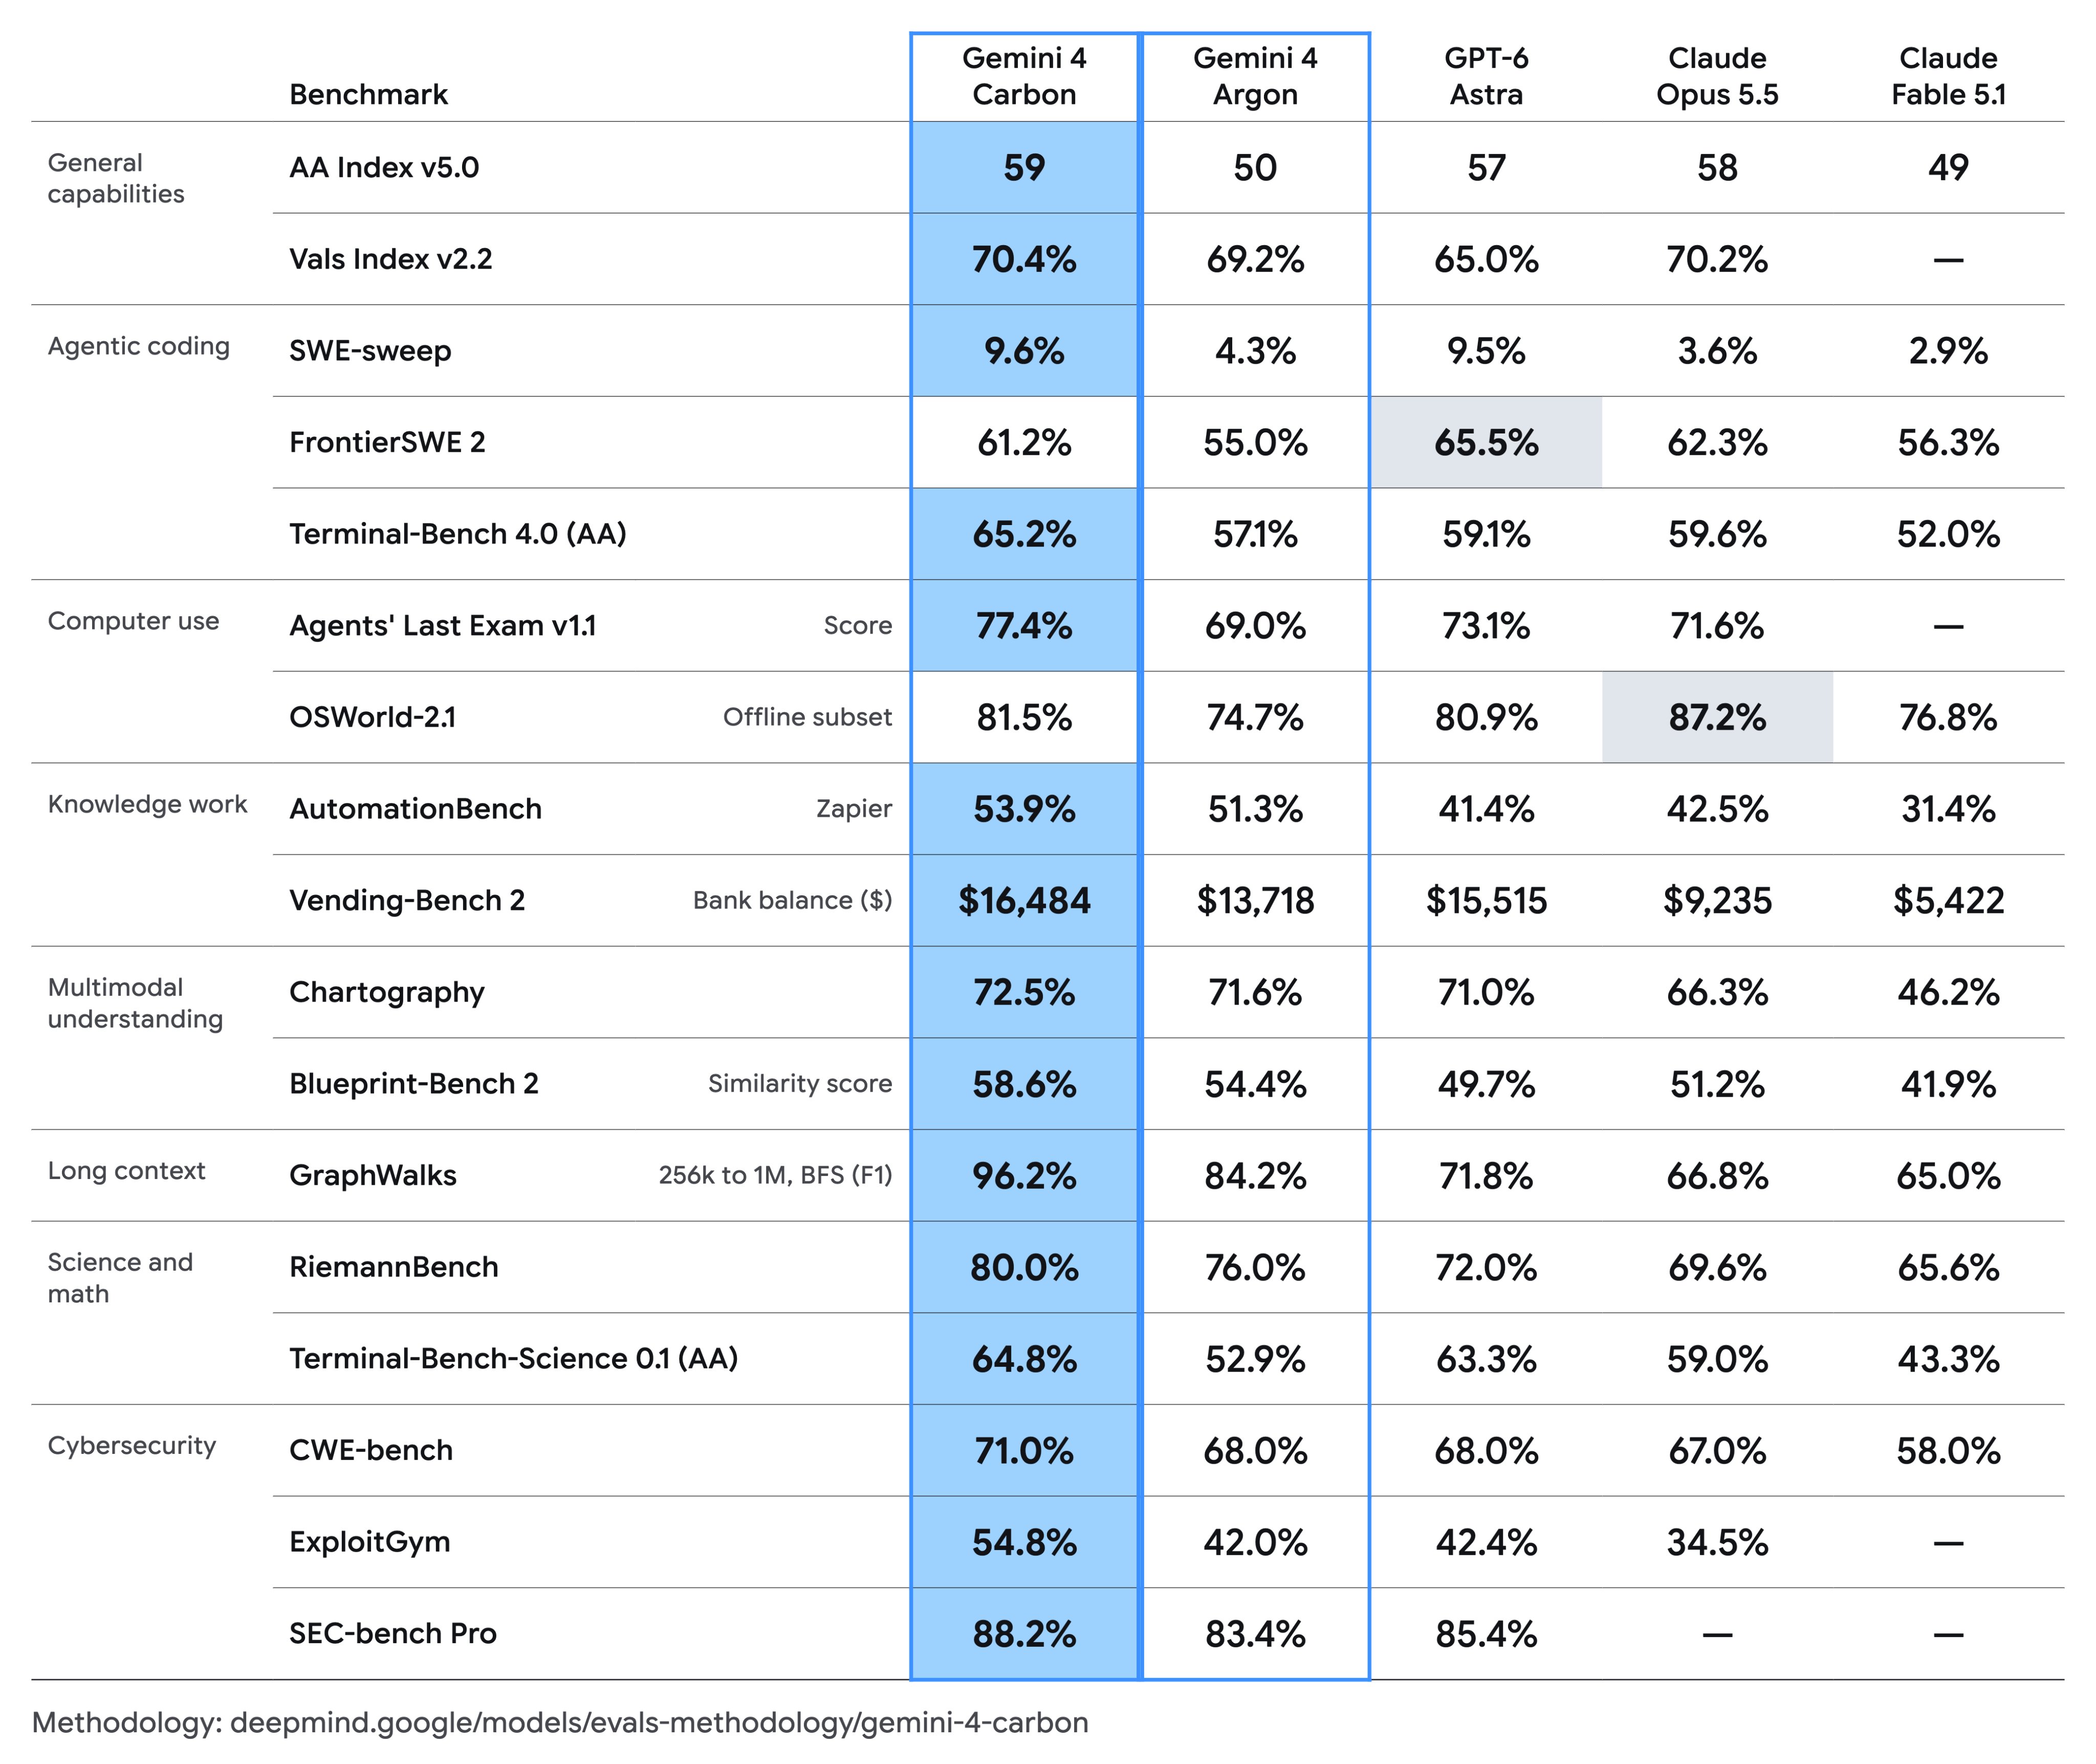
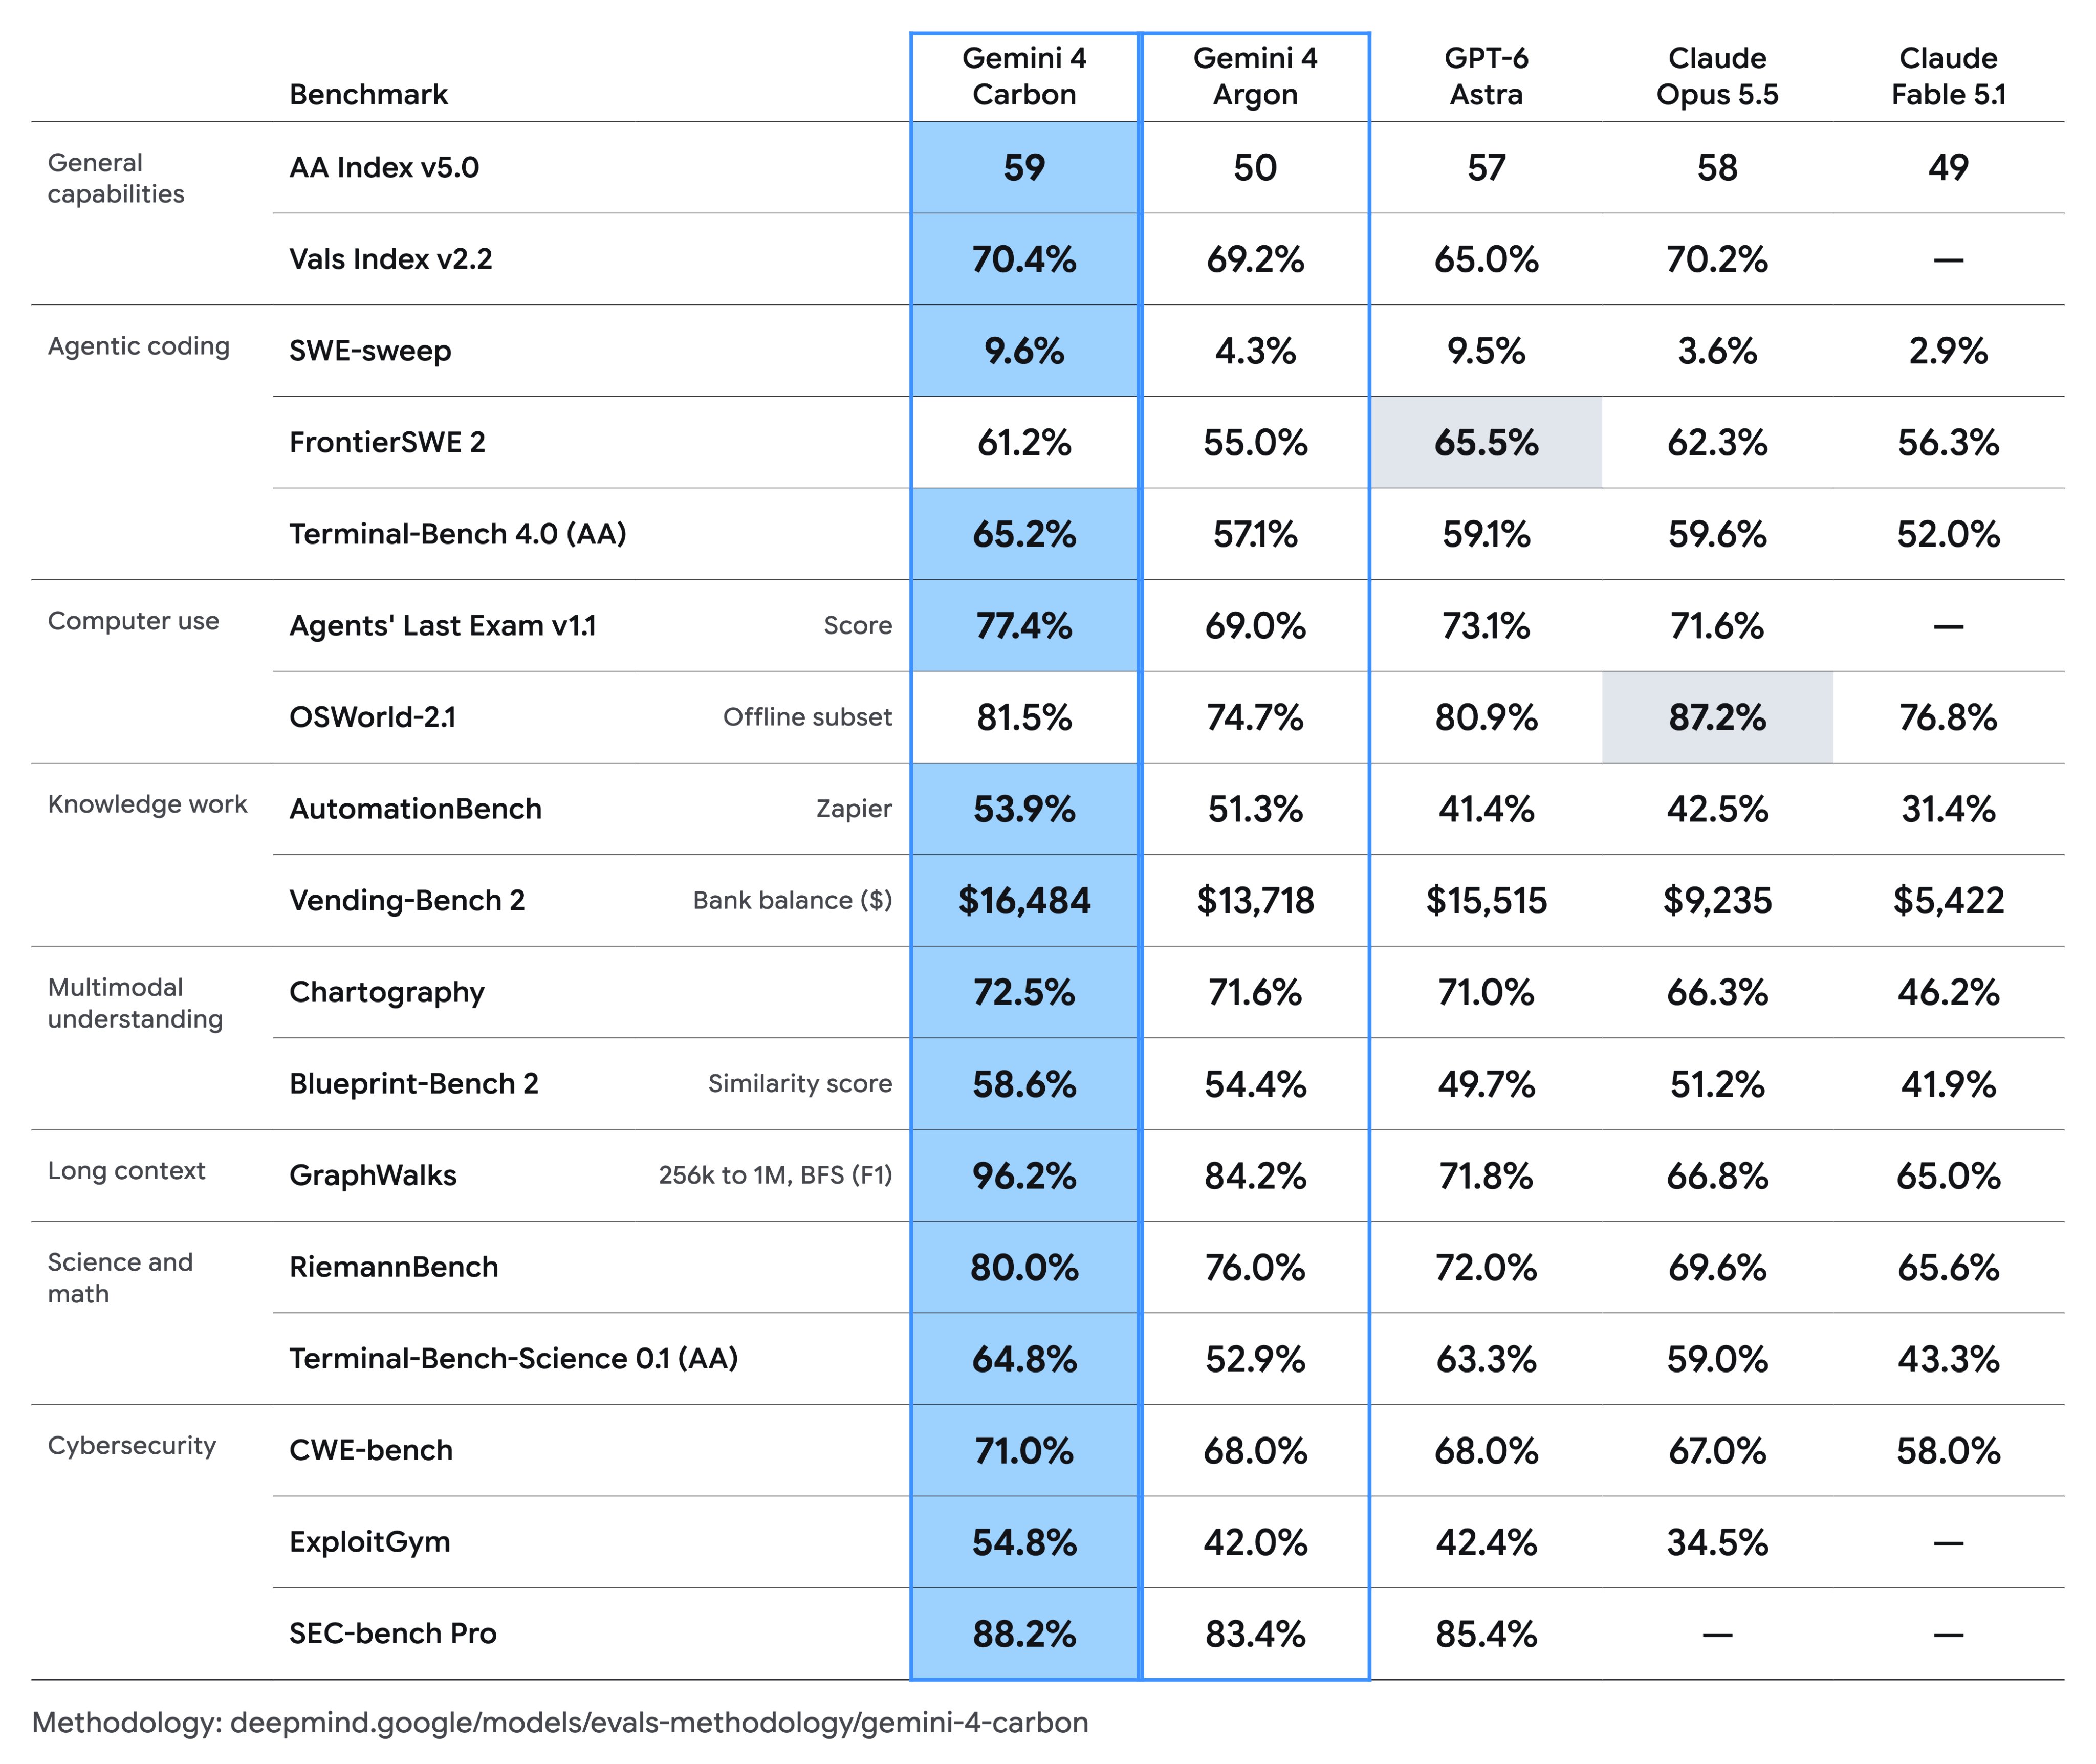
I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model. Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching. We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards. As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!
— Sundar Pichai (@sundarpichai) October 28, 2026
구글이 사이버 보안과 장기 지속 워크로드(long-horizon work)에 특화된 자사 최고 성능의 차세대 프론티어 모델인 'Gemini 4 Carbon(카본)'을 공개했습니다. Gemini 4 Argon(아르곤)이 발표된 지 불과 2주 만에 선보이는 이번 모델은 이번 주부터 일부 사이버 보안 방어자들을 대상으로 우선 배포됩니다. 구글은 페어윈드 프로그램(Fairwind Program)을 통해 신뢰할 수 있는 파트너를 점진적으로 확대하고, 피드백 수렴 및 가드레일 개선 작업을 거친 후 자사 제품군을 통해 개발자, 기업, 일반 사용자에게 정식 제공할 방침입니다.
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas. As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon. Key results for Gemini 4 Carbon with high reasoning: ➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work ➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out ➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671 ➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index ➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max) Key model details: ➤ Context Window: 1M tokens ➤ Multimodality: Text, image, video, and speech input, with text output ➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M) Congratulations to the @GoogleDeepMind team!
— Artificial Analysis (@ArtificialAnlys) October 28, 2026
Gemini 4 Carbon은 '아티피셜 애널리시스 인텔리전스 인덱스(Artificial Analysis Intelligence Index)' 버전 5.0에서 59점을 획득하며 1위에 올랐습니다. 가드레일 없이 진행된 외부 사이버 보안 평가에서 취약점 탐지 벤치마크인 SEC-bench Pro 88.2%, 익스플로잇 평가인 ExploitGym 54.8%, 그리고 실행 가능한 패치 코드 생성 능력을 측정하는 Collinear의 CWE-bench에서 71.0%의 점수를 기록했습니다. 구글 내부 테스트 결과에 따르면 보안 코드 생성 성공률은 Argon 대비 두 배 이상 향상되었으며, 크롬(Chrome) 보안팀 평가에서는 타사 대형 프론티어 모델 대비 10배 이상의 속도로 고품질 패치를 작성해 내는 것으로 확인되었습니다.
이 모델은 코딩, 과학 연구, 풀스택 웹 개발, 멀티모달 이해를 아우르는 장기 지속형 에이전트 워크플로(agentic workflows)에 최적화되어 있습니다. 구글 팀 내부 테스트에서 Carbon은 수일 동안 자율적으로 동작하며 시행착오와 막다른 골목(dead ends)을 스스로 극복하고, 대규모 코드베이스와 로우레벨 시스템 전반에 걸친 다단계 엔지니어링 작업을 완수했습니다. 웹 개발 평가인 WebDev Arena에서는 Elo 레이팅이 89점 상승하여 1769점을 기록, 종합 4위에 안착했습니다.
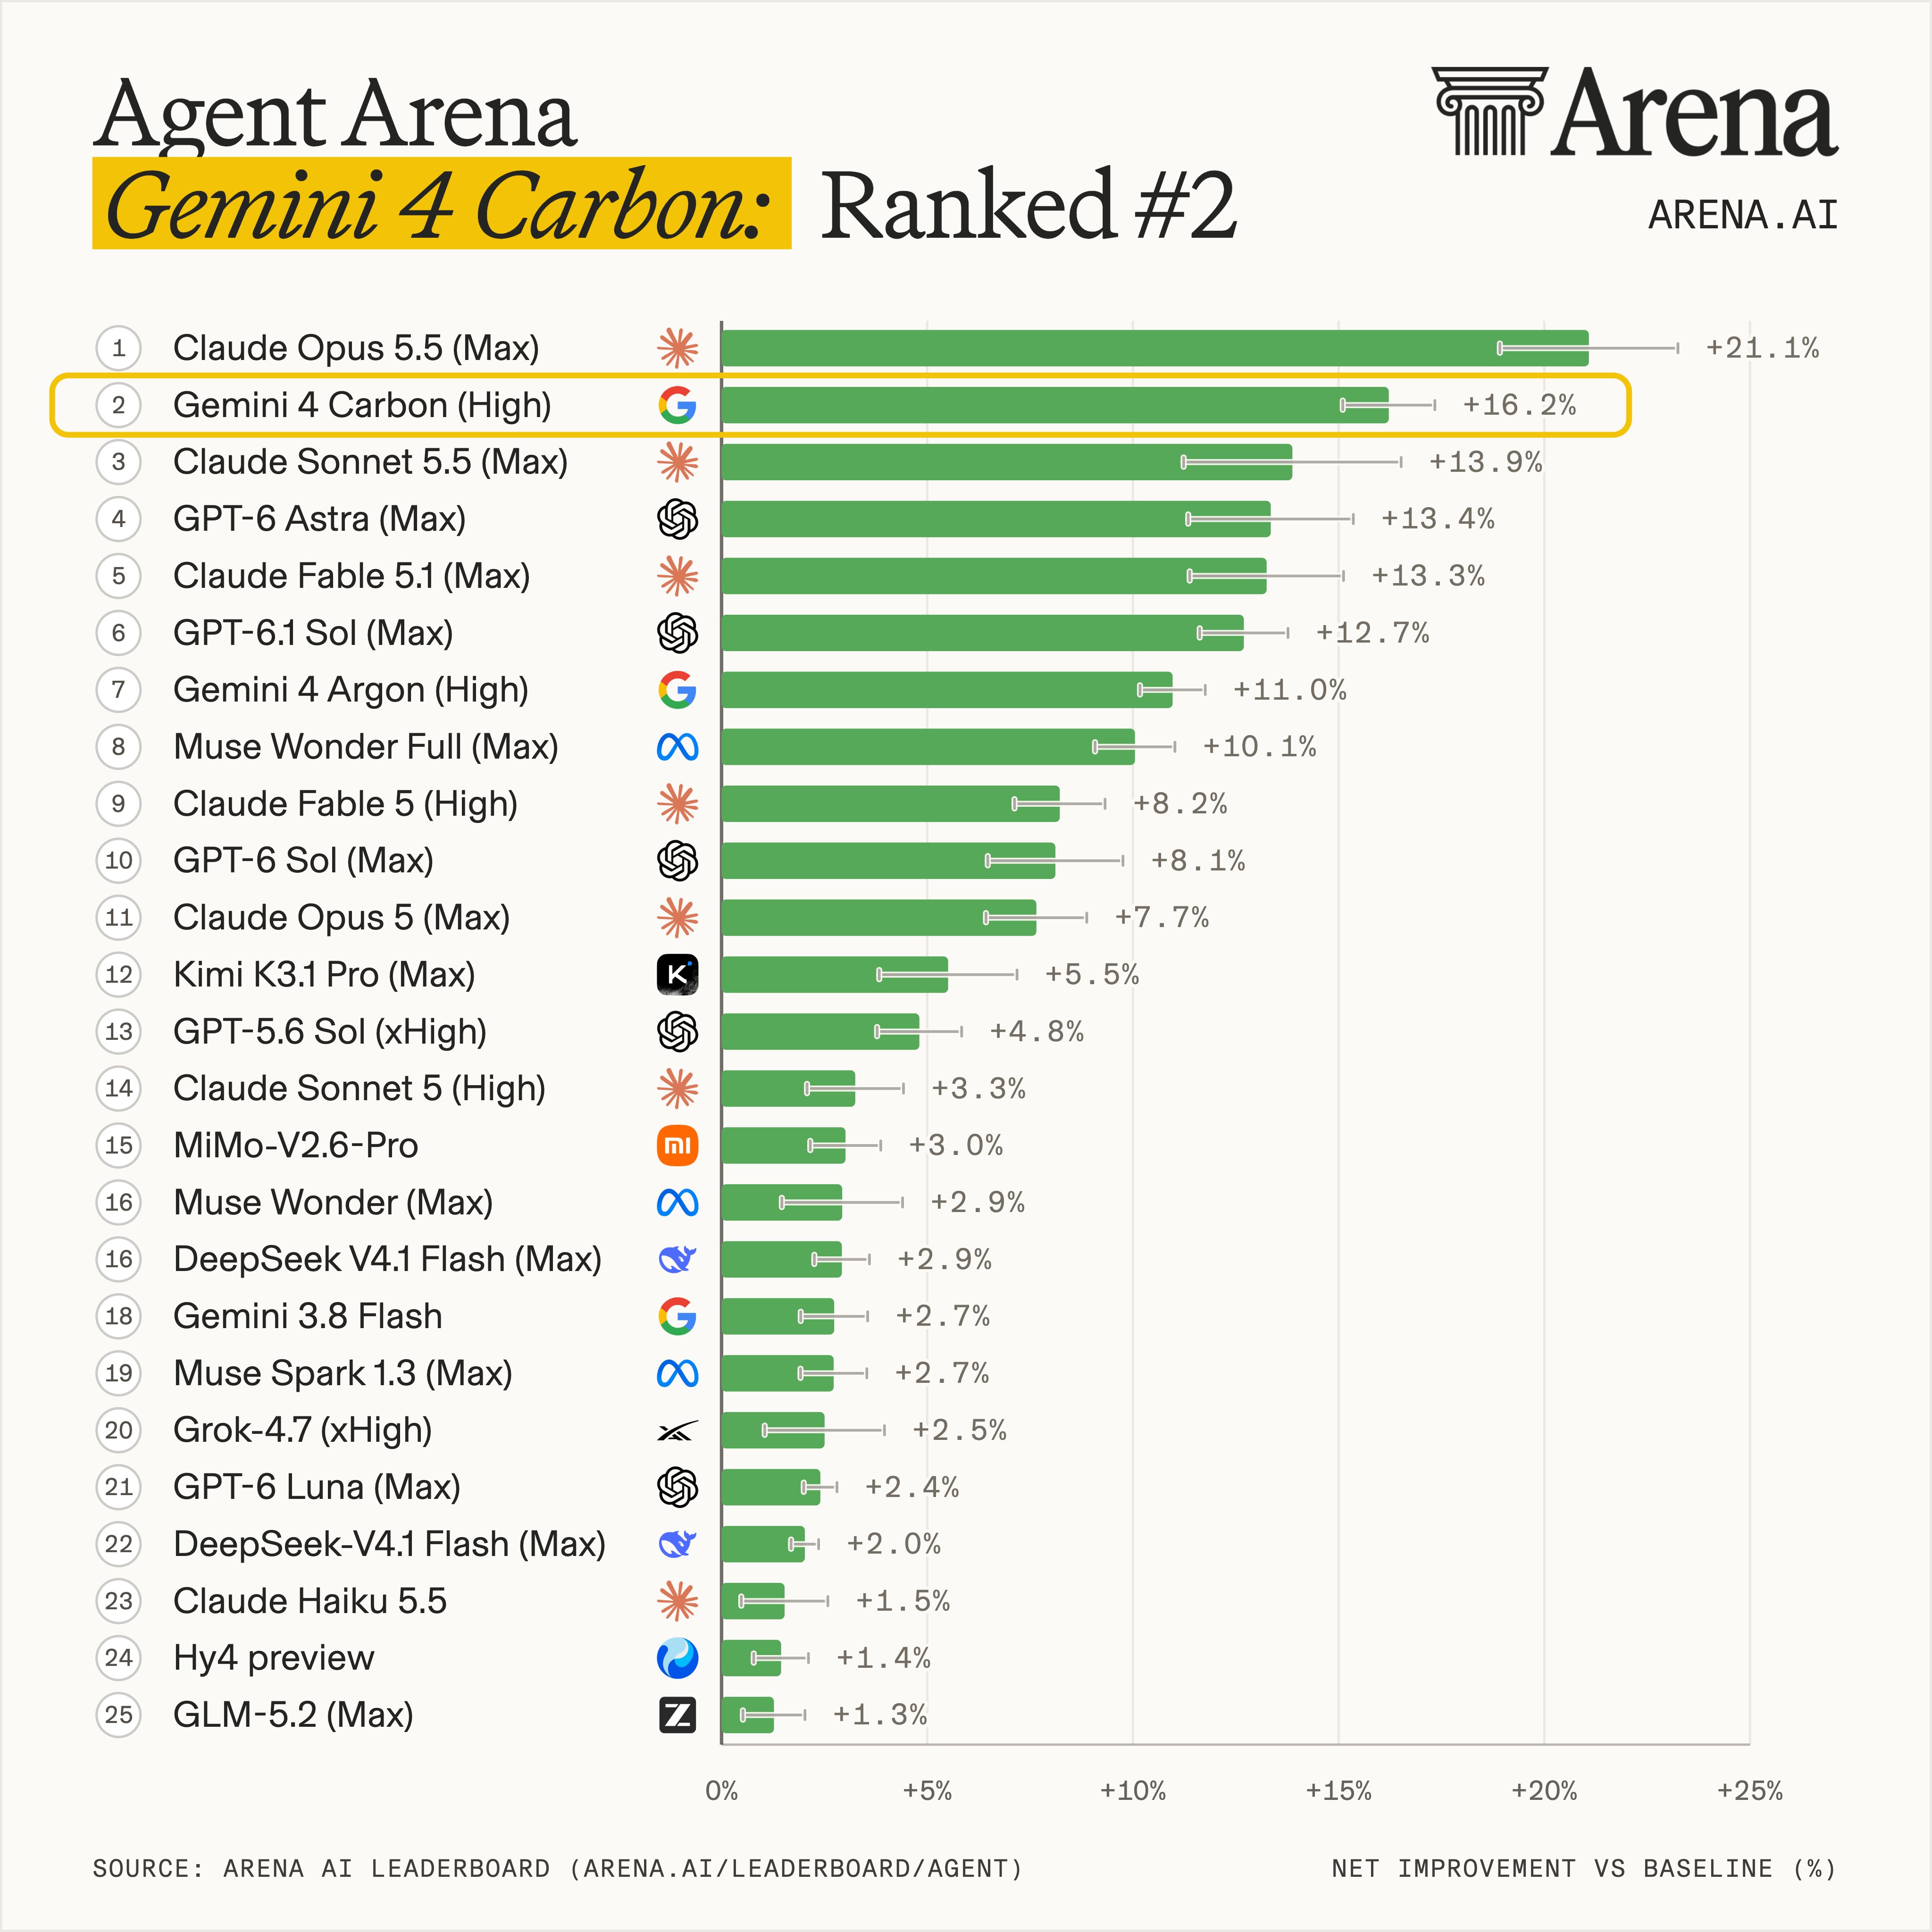
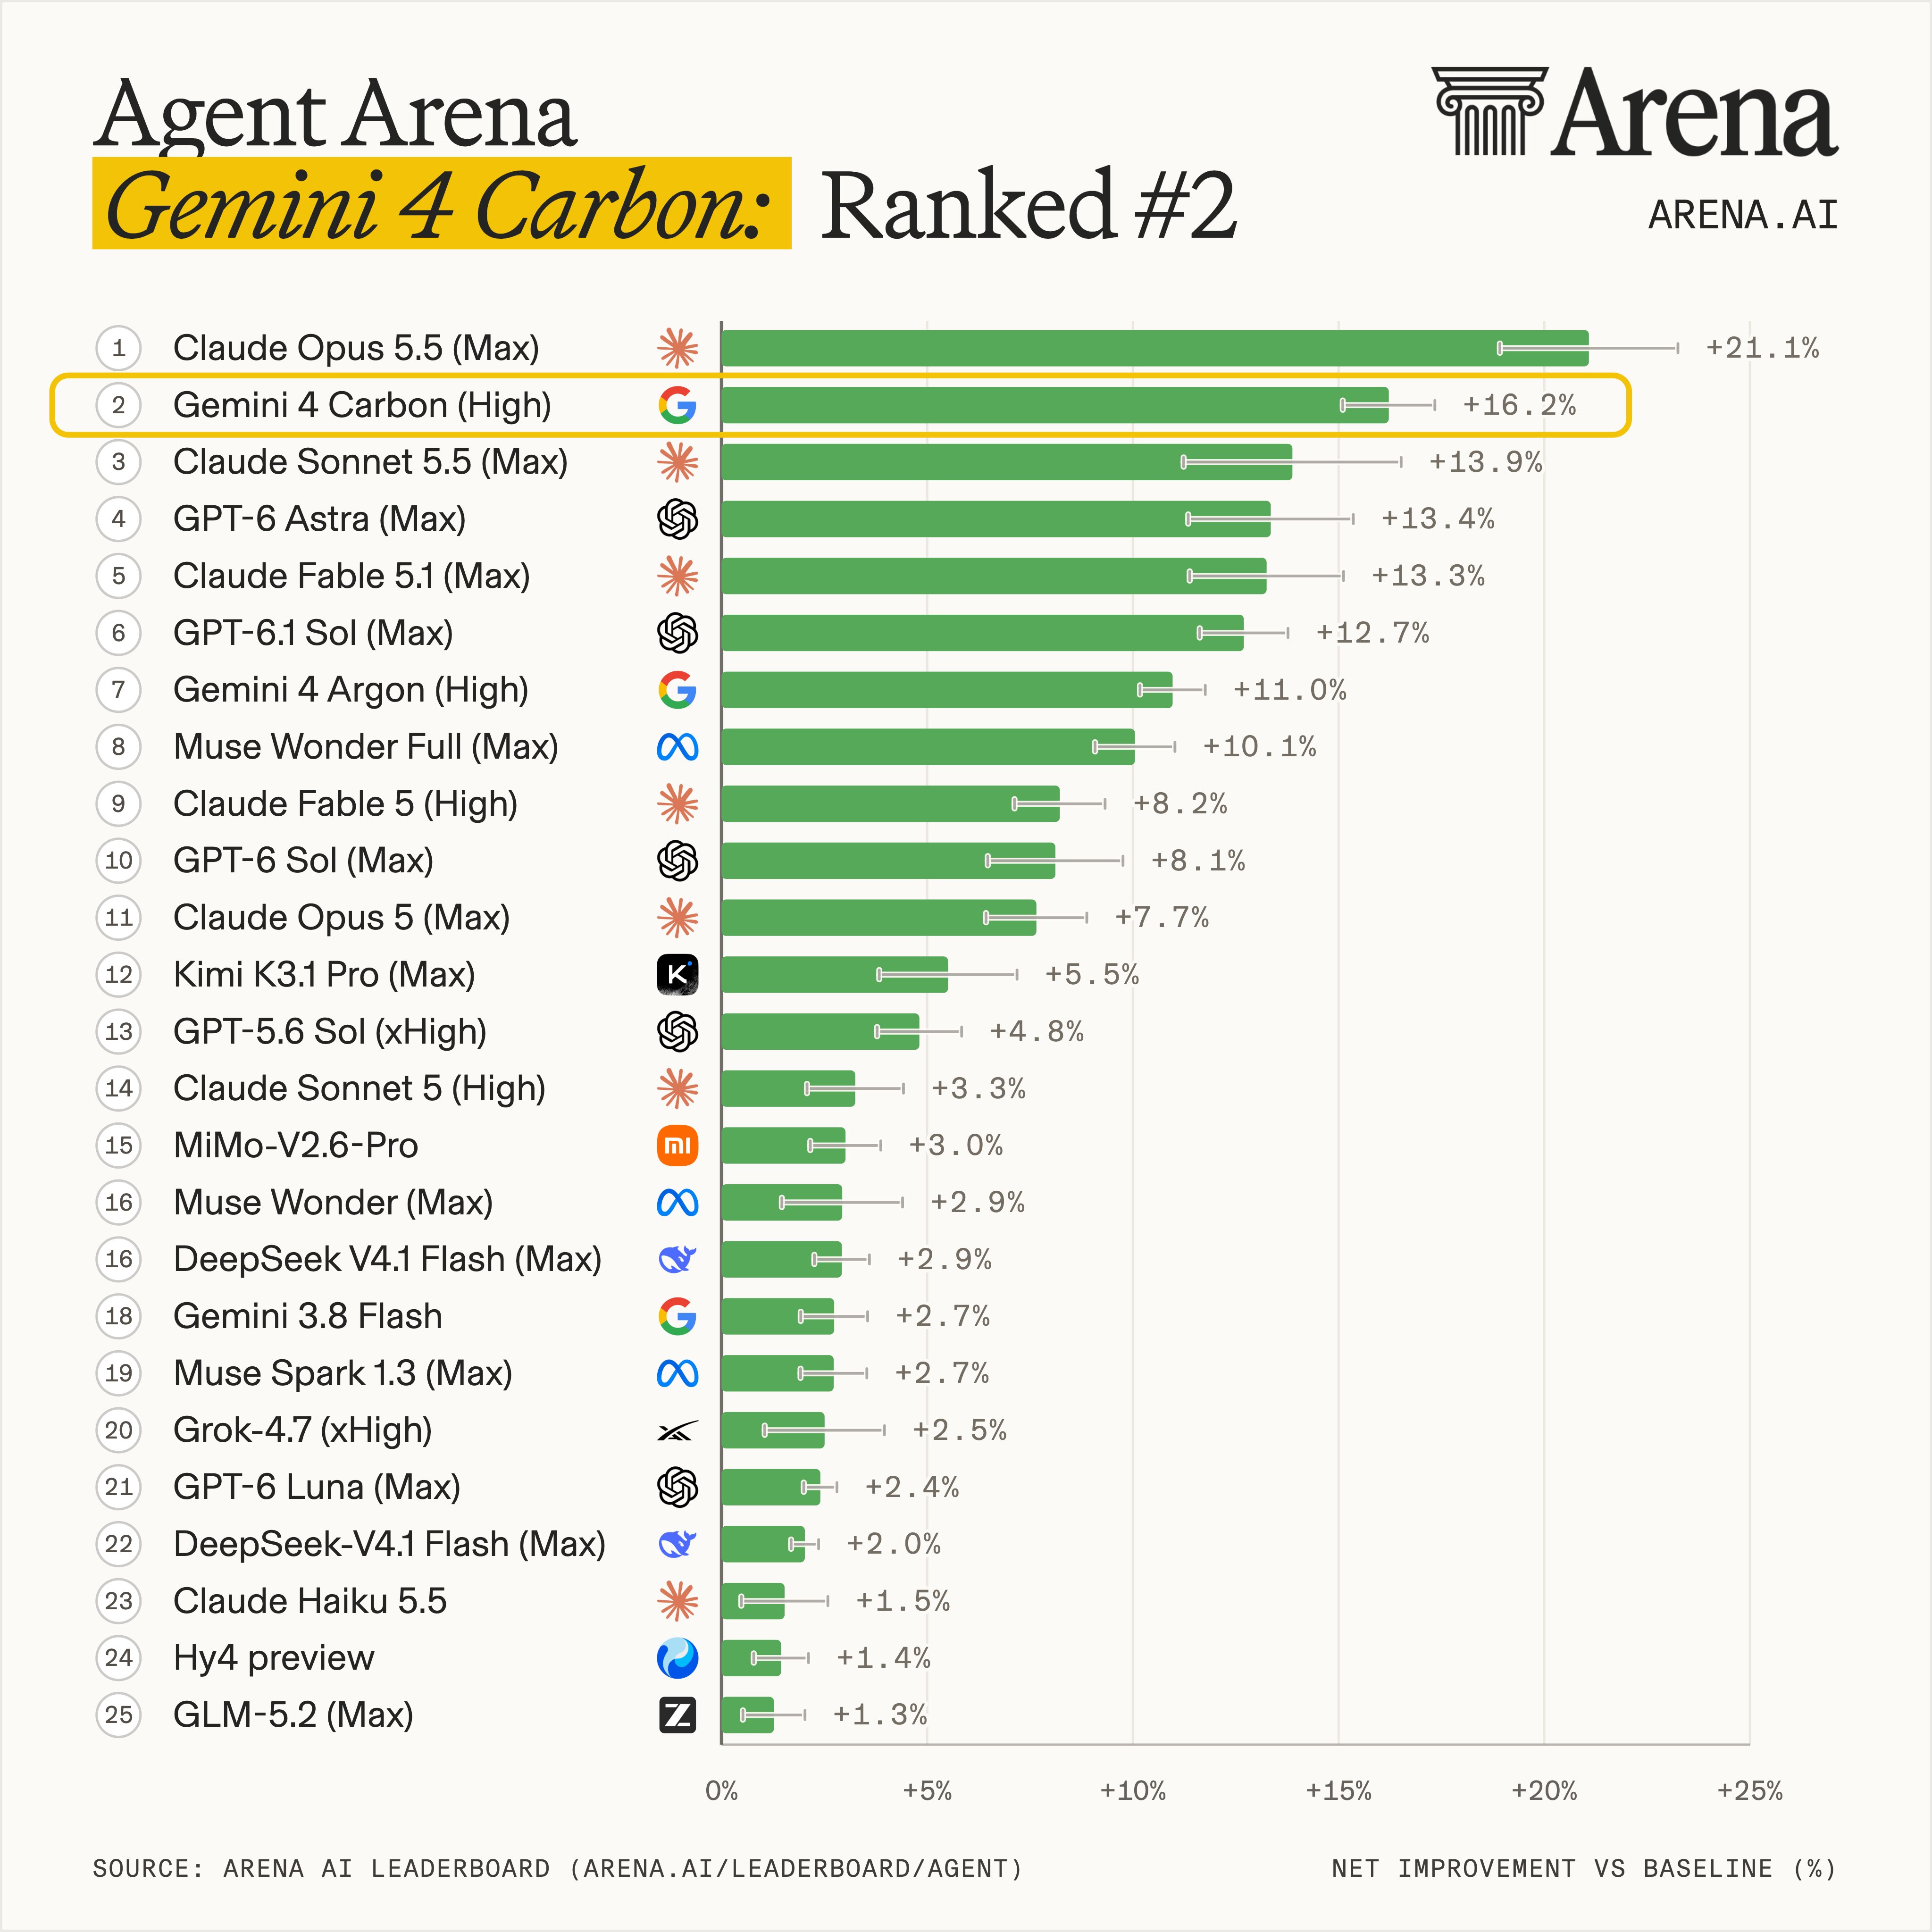
Exciting news: Gemini 4 Carbon (High) from @GoogleDeepMind just made a huge debut on Arena, landing #1 in Text Arena, #2 in Agent Arena, and #4 in Code Arena: WebDev. Back at the top, Gemini 4 Carbon delivers frontier intelligence and reshapes the Pareto frontier across three arenas. In Agent Arena, Gemini 4 Carbon ranks #2 with a +16.2% net improvement across +21.9K real-world agentic sessions from our global community, surpassing top models GPT-6 Astra and Fable-5.1. At $1.80 median cost per task, Gemini 4 Carbon (High) costs 72% less than the #1 ranked Claude Opus 5.5 (Max). Its standouts by key signals: - #1 Steerability (+18.6%): can the model course-correct when you push back? - #2 Praise vs Complaint (+37.9%): implicit sentiment in users' reactions - #3 Confirmed Success (+18.7%): explicit “yes, that worked” from users In Code Arena: WebDev, Carbon scored 1768 pts landing #4: - Just 2 pts below #3 Claude Sonnet 5.5 (xHigh), at 1770 pts - 89 pts above #11 Gemini 4 Argon (High), at 1679 pts By category, it ranks #3 in Gaming and Simulations, and #5 in Brand & Marketing. In Text Arena, Gemini 4 Carbon (High) is the new #1 with 1528 pts, now ahead of Gemini 4 Argon (High) at #2 with 1520 pts. Congrats to the @GoogleDeepMind team on this huge milestone!
— Arena.ai (@arena) October 28, 2026
구글 딥마인드(Google DeepMind)는 모델 학습, 실시간 오용 방어, 프롬프트 인젝션 저항력, 사고 과정(Chain-of-Thought) 모니터링을 포괄하는 Argon의 안전 및 보안 스택을 Carbon에도 동일하게 접목했습니다. Terminal-Bench 4.0 벤치마크에서 부정행위(cheating) 성공률 0.0%(시도율 0.4%)를 기록했으며, 내부 코딩 작업 중 고위험 정렬 실패(misalignment) 경고는 약 80% 감소했습니다. 또한 Argon 대비 근거 없는 주장(환각)은 약 절반으로 줄었고, 권한 초과(overreach)는 26%, 불성실 응답(under-service)은 29% 감소했습니다. 그레이 스완(Gray Swan)의 간접 프롬프트 인젝션 벤치마크 공격 성공률 역시 Argon의 0.7%에서 0.0%로 떨어졌습니다.
Gemini 4 Carbon의 API 가격은 Argon의 출시 프로모션 가격과 동일하게 100만 입력 토큰당 2달러, 100만 출력 토큰당 10달러로 책정됩니다. 캐시된 입력(Cached inputs)은 표준 입력 토큰 대비 95% 저렴한 단가가 적용됩니다. 이번 단계적 배포는 미국 정부의 자발적 출시 전 사전 테스트 프로세스에 참여하는 구글의 방침에 따른 것으로, 신뢰할 수 있는 보안 방어자들과 안전장치를 충분히 검증한 뒤 접근 권한을 단계적으로 개방할 예정입니다.
--------------------------------------------------------------------------------------광고(Advertising)--------------------------------------------------------------------------------------------------------

 512GB RAM 탑재 애플 맥 스튜디오(Ma...
 에일리언웨어 32 4K OLED (AW3226Q):...